
Financial systems can’t tolerate the standard chaos engineering playbook as written. Most guides tell you to pick a service, kill a pod, and watch what happens in production. That advice assumes the worst outcome is a dashboard turning red and an on-call engineer getting paged. In a payments platform, the worst outcome is a duplicated transfer, a stuck settlement batch, or a regulator asking why your resilience testing moved real customer funds. The tooling for chaos engineering is mature. The judgment required to run it against a ledger is not something most of that tooling was built to enforce.
This matters because the alternative to controlled chaos testing isn’t safety, it’s untested failure modes surfacing during an actual outage. Platform teams at fintech companies are stuck between two risks: breaking something in production on purpose, or finding out during a real incident that a dependency fails in a way nobody modeled. The way out is building failure injection with the same rigor you’d apply to the production system itself: scoped, audited, and reversible.
Why Chaos Engineering Needs a Different Playbook in Finance
Standard chaos engineering treats blast radius as a tuning parameter: start small, expand as confidence grows. In most SaaS products, an overly broad experiment costs you an availability SLA and an apology email. In a financial system, an overly broad experiment can touch money movement, trigger a false fraud alert that locks out thousands of customers, or generate a PCI-DSS scope violation because a chaos agent ran inside a cardholder data environment without the right controls around it.
The regulatory layer changes the engineering problem. SOC 2, PCI-DSS, and in many jurisdictions banking-specific operational resilience rules all expect you to demonstrate that failure testing is controlled, logged, and reviewable after the fact. That means every experiment needs a paper trail that a risk officer can read without needing to understand Kubernetes. The playbook for finance isn’t more cautious chaos engineering, it’s chaos engineering redesigned around approval, isolation, and proof.
Defining Blast Radius: What You’re Allowed to Break and What You Aren’t
Blast radius in a financial system has to be defined before anyone writes an experiment, not discovered during one. That means building an explicit allowlist of what failure injection is permitted to touch, and treating everything else as off-limits by default rather than by convention.
A workable blast radius policy usually separates the production environment into three categories:
- Freely testable: stateless services with no write path to a ledger, read replicas serving cached data, internal tooling.
- Testable with isolation: services that touch money movement but can be exercised through synthetic transactions tagged and routed separately from real ones.
- Never touched in production: the ledger of record, settlement batch processors, anything that initiates an irreversible transfer, and any system still inside active PCI-DSS or SOC 2 audit scope unless the experiment itself has been pre-approved as part of that scope.
The enforcement for this can’t live in a wiki page. It needs to live in the failure injection tooling itself, as a hard check against a service registry that tags each component with its blast radius category. If the tooling can’t resolve a target’s category, the experiment should fail to launch rather than default to permitted. This is the same logic you’d apply to any privileged action against production: deny by default, and make the allow path explicit and logged.
Isolating Chaos Experiments From Real Money Movement
The single most important design decision in financial chaos engineering is keeping synthetic load fully separate from real transaction flow, end to end, not just at the point of injection.
This usually means:
- Synthetic account identities that are structurally indistinguishable from real customer accounts in format, but flagged at creation with a marker that every downstream system, including fraud detection and AML monitoring, is built to recognize and exclude from real reporting.
- A shadow settlement path for any experiment that needs to exercise the full transaction lifecycle, including a mock downstream rail that acknowledges or fails on command without touching an actual banking partner or card network.
- Tagging that survives serialization. If a synthetic transaction gets published to an event stream, logged into a data warehouse, or picked up by a fraud model for scoring, the tag needs to travel with it, not get stripped at the first service boundary.
The failure mode to watch for is a synthetic transaction that looks real by the time it reaches a system that wasn’t built with chaos testing in mind, like a regulatory reporting pipeline that assumes every transaction it sees is genuine. Audit the tag propagation the same way you’d audit a bug: trace a synthetic transaction through every service it touches and confirm the marker is still attached at each hop before you let an experiment run unsupervised.
Building Automated Failure Injection Into Your CI/CD Pipeline
Manual chaos experiments don’t scale, and they don’t generate the consistent evidence trail an audit expects. The goal is to make failure injection a scheduled, versioned part of the deployment pipeline, with the same change control as a code release.
A practical setup looks like:
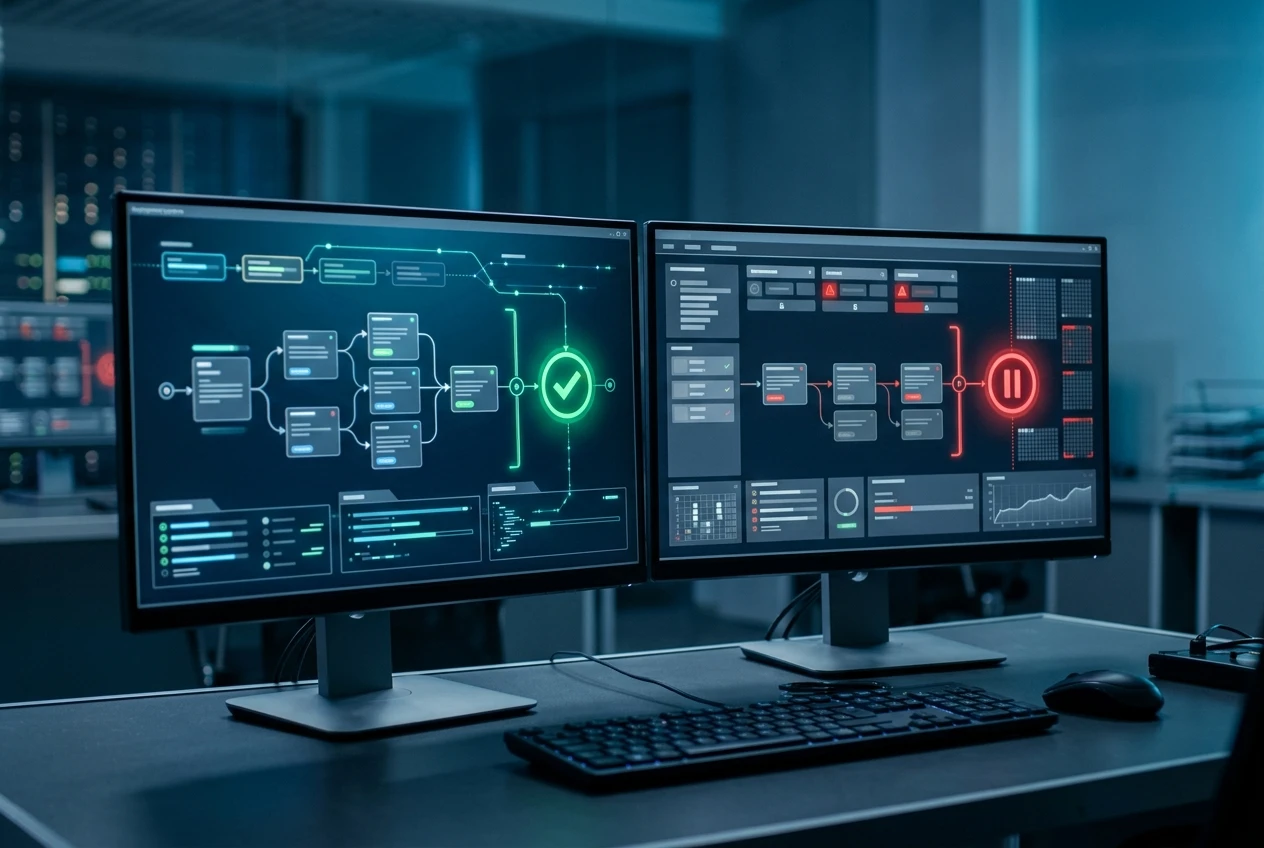
- Experiments defined as code, stored in version control, with a required reviewer the same way a production deploy requires one.
- A gate that checks the target’s blast radius category and synthetic transaction isolation status before the experiment is allowed to run, failing closed if either check can’t be verified.
- Scheduled runs against staging and pre-production environments on every merge, with production runs restricted to an approved, lower-frequency window that compliance has signed off on in advance.
- Automatic rollback triggers tied to real business metrics, not just infrastructure health, so an experiment that starts affecting transaction success rate or latency beyond an agreed threshold halts itself rather than waiting for a human to notice.
Treating chaos experiments as pipeline artifacts also means you get the same audit trail you already have for deployments: who approved it, when it ran, what it targeted, and what the rollback condition was. That reuse of existing CI/CD governance is what makes this approach defensible to a compliance team, because you’re not asking them to trust a new process, you’re extending one they already understand.
Running Chaos Experiments Inside a PCI-DSS Scope Without Breaking It
Any experiment that targets infrastructure inside PCI-DSS scope needs to be treated as a change to that scope, because in practice it is one. The chaos injection agent itself, if it runs as a sidecar or privileged process inside a cardholder data environment, becomes part of the environment an auditor will ask about.
The safest pattern is to keep the injection control plane entirely outside PCI-DSS scope and have it act on in-scope workloads through the same orchestration layer you already use for deployments, rather than installing a separate agent inside the scoped environment. If you’re running chaos experiments against containerized workloads that sit inside your PCI-DSS boundary, the orchestration controls that keep that boundary defensible are the same ones that need to govern how an experiment gets admitted, scheduled, and logged; the practices covered in container orchestration that passes a PCI-DSS audit apply directly to how you scope a chaos injection agent’s access.
Testing Failure Modes in Event-Driven Payment Pipelines
Event-driven payment systems fail in ways that are hard to reproduce with a simple pod kill: a consumer group rebalances mid-processing, a message gets delivered twice, a downstream service falls behind and the queue backs up past its retention window. These are exactly the failure modes that matter most in production and are hardest to test safely, because the natural way to trigger them is to interfere with the actual event stream carrying live transactions.
Synthetic transaction isolation solves most of this, provided the event schema and routing were designed with it in mind from the start. If synthetic events carry the same tag through the broker, through every consumer, and into every downstream sink, you can inject duplicate messages, delayed consumers, or out-of-order delivery against the real infrastructure without a real transaction ever being at risk. The architectural decisions that make this possible, like how partitioning and consumer group design handle backpressure and replay, are the same ones covered in designing fault-tolerant event-driven pipelines for real-time financial data, and it’s worth revisiting that design with chaos testing specifically in mind rather than treating fault tolerance and chaos testing as separate projects.
Metrics That Prove Resilience to Auditors, Not Just to Yourself
An SRE team and a compliance team want different evidence from the same experiment. The SRE team wants to know whether the system degraded gracefully. The compliance team wants to know whether the experiment was controlled, whether it stayed inside its approved blast radius, and whether anything it touched could plausibly have affected a real customer or a real transaction.
Metrics worth capturing for every experiment, structured so a non-engineer can read them:
- What was targeted, and which blast radius category it fell under.
- Confirmation that all transactions involved were tagged synthetic, with a count.
- The approved rollback condition, and whether it was triggered.
- Time to detect the injected failure through existing monitoring, separate from time to recover.
- Any monitoring or alerting gap the experiment exposed, logged as a finding regardless of whether the system itself recovered cleanly.
That last point matters more than it looks. An experiment where the system recovered but nobody’s alert fired is a worse outcome than an experiment where the system struggled but was detected immediately, because the first one means you’d have found out about a real failure from a customer complaint instead of a dashboard.
Turning Chaos Findings Into a Living Incident Runbook
A chaos experiment that doesn’t change anything downstream of it was a wasted exercise. Every finding, whether it’s a missing alert, a slow failover, or a dependency that behaved differently than documented, should feed directly into the incident runbook that the on-call team actually uses during a real event.
The link works best when it’s structural rather than manual: each chaos experiment definition references the runbook section it’s meant to validate, and a failed or surprising result flags that section as needing a rewrite rather than leaving a stale document sitting next to an outdated understanding of how the system behaves. Over time, the runbook stops being a document written after incidents and becomes one that’s been exercised before any of them happen, which is the actual evidence a risk team wants to see: not that you can describe your failure modes, but that you’ve triggered them on purpose and know exactly what happens next.