
Data residency rules get written at the policy level and enforced at the database level, and that gap is where most fintech compliance programs quietly fail. A legal team can draw a map showing which country’s data stays in which country. An infrastructure team can stand up data centers in each of those countries. Neither of those steps tells you which row of which table physically sits on which disk, and that is the question a regulator actually asks.
This piece picks up where the centralized versus regional architecture question leaves off. Choosing regional data centers over a centralized one gets you the right buildings in the right countries. It does not get you a system that reliably puts a German customer’s transaction history in a German building and keeps it there through every backup, replica, and log line that system generates. That second problem is a data modeling problem, and it’s solved inside the database, not around it.
What data residency rules actually require at the row level
Most data residency language, whether it comes from GDPR, India’s data protection framework, or a central bank’s localization mandate, specifies that certain categories of personal or financial data must be stored, and often processed, within a jurisdiction’s borders. The regulation does not care about your data center footprint as an abstraction. It cares about where the bytes representing a specific customer’s specific record live at rest, and in some regimes, where they live during processing too.
This is a row-level requirement dressed up in data-center-level language. If you have a customers table with ten million rows, a compliant architecture is not “we have a data center in Frankfurt.” It’s “every row belonging to a German data subject is stored on infrastructure inside Germany, every time, including the copies.” Most teams build the first thing and assume it satisfies the second. It doesn’t, and the gap only becomes visible during an audit or a breach, which is the worst possible time to discover it.
The practical consequence is that residency compliance lives in your schema and your routing logic, not in your deployment diagram. You need a reliable, enforceable answer to “which jurisdiction does this row belong to” for every table that touches personal or financial data, not just the obvious ones.
Mapping your schema to jurisdictions before you choose a shard key
Before any sharding decision, you need a jurisdiction map of your own schema. This is tedious work and it’s also the part that determines whether everything downstream actually holds up.
Walk every table that contains personal data, financial data, or anything derived from either, and ask which jurisdiction each row’s data subject belongs to. For a customer record this is usually straightforward: it’s tied to the customer’s declared residency or the entity that onboarded them. For derived or joined data, it gets harder. A transaction record involves a sender and a receiver who may be in different jurisdictions. A fraud score might be computed from inputs spanning three countries. A support ticket might quote a transaction ID that lets someone reconstruct a customer’s financial history regardless of where the ticket itself is stored.
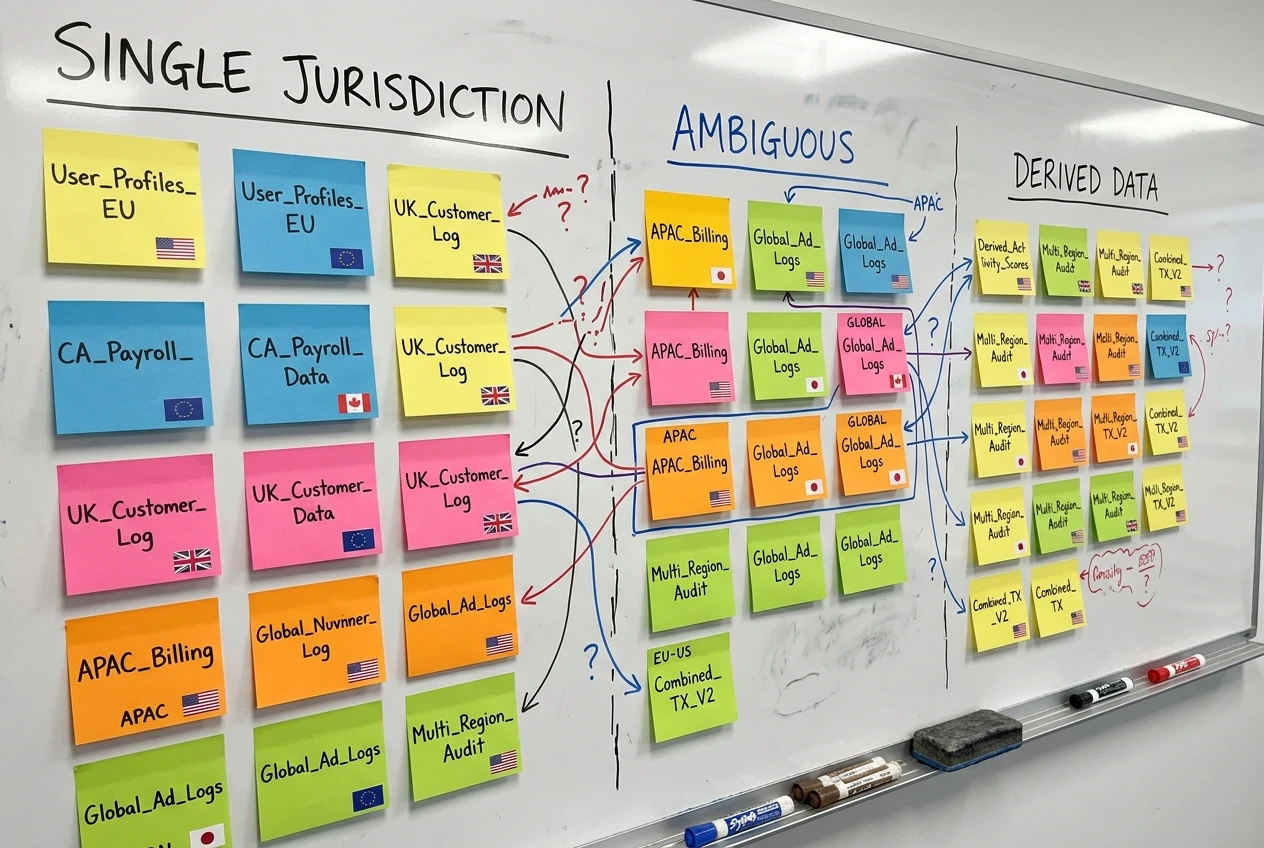
The output of this exercise should be a table-by-table list marking which tables have a clean, single-jurisdiction owner per row, which have ambiguous or multi-jurisdiction rows, and which are derived from residency-governed data without themselves being obviously governed. That third category is where most compliance gaps live, because engineers naturally think about residency for primary records and forget that anything joined, aggregated, or cached from those records inherits the same obligation.
Only once this map exists does a shard key choice mean anything. Picking a shard key without this map is picking a lock before you know what door it goes on.
Picking a shard key that survives a regulator’s audit, not just your query patterns
Database teams default to choosing a shard key for query performance: something with good cardinality, even distribution, and a natural fit with the application’s hot paths. For a residency-driven system, that default is the wrong starting point.
The shard key has to encode jurisdiction, directly or through a lookup that’s itself auditable. There are generally two viable approaches:
- Jurisdiction as a literal component of the key. A composite key like
(country_code, customer_id)makes the jurisdiction visible in every query and every piece of routing logic. An auditor can look at the key and verify the row lives where it should without tracing application code. - Jurisdiction resolved through a reference table. The shard key is something like
customer_id, and a separate, tightly controlled mapping table resolves each customer to a jurisdiction and therefore a shard. This decouples the key from the jurisdiction, which helps if a customer’s residency status can change, but it means your audit trail now depends on that mapping table being correct, versioned, and itself properly located.
The literal approach is easier to defend to a regulator because the proof is structural rather than procedural. The reference-table approach is easier to live with operationally because it handles the edge case of a customer relocating without a schema migration. Most mature fintech systems end up using a hybrid: a literal jurisdiction field in the key for the tables that matter most, backed by a reference table for the harder, multi-party cases like cross-border transactions.
Whichever you choose, write down the decision and the reasoning. An auditor doesn’t just want a working system; they want evidence that jurisdiction was a deliberate input to the schema design, not a retrofit.
Running localized storage nodes without splitting your application logic into forks
The operational trap in data residency work is solving it by writing different code for different regions. A conditional that says “if customer is in India, write to the India cluster using this slightly different function” feels pragmatic in week one and becomes an unmaintainable fork within a year, because every new feature now needs to be built and tested against N regional variants.
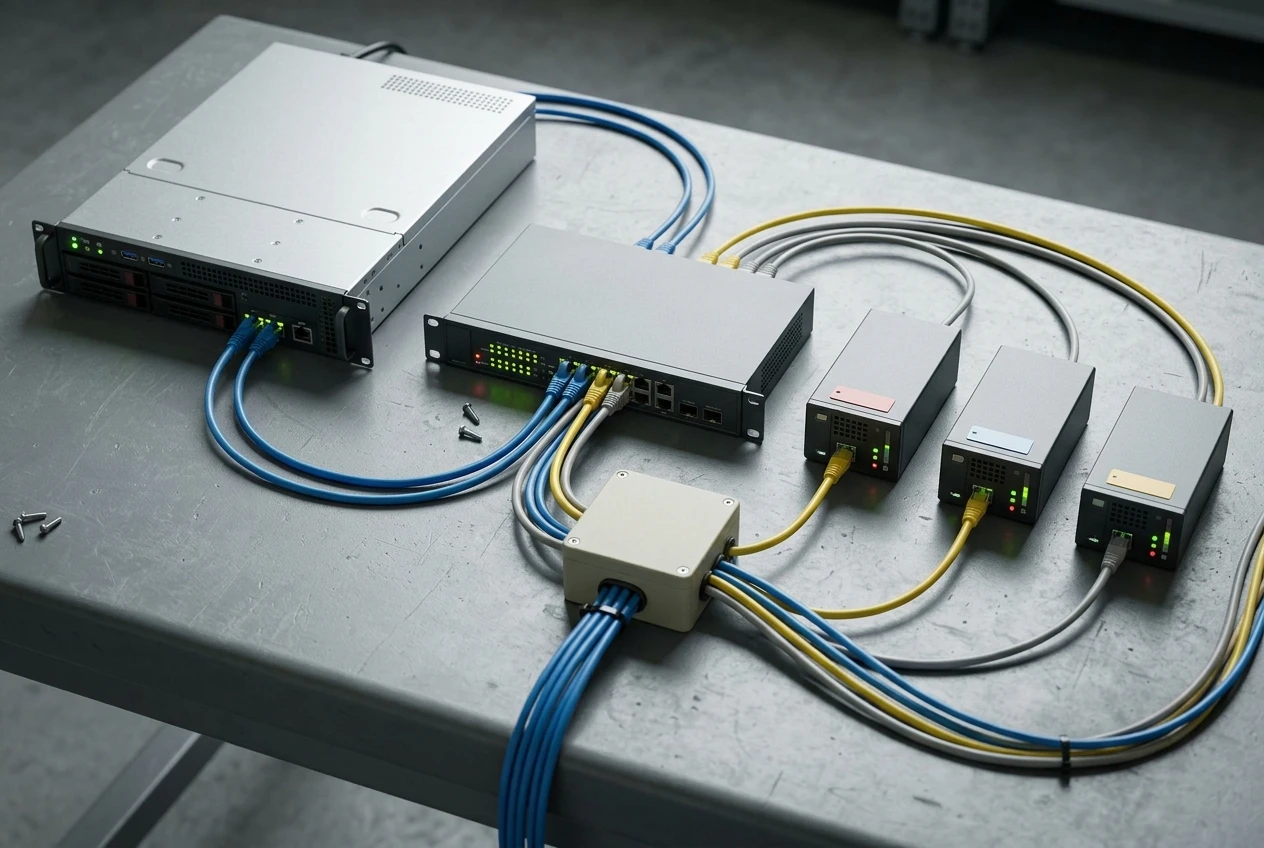
The more durable pattern is to keep a single application codebase and push jurisdiction-awareness down into a routing layer that sits between the application and the storage nodes. The application writes a customer record the same way regardless of where that customer lives; the routing layer, informed by the shard key or the jurisdiction reference table, decides which physical node receives the write. Reads work the same way in reverse: the application asks for a customer record, and the routing layer resolves which node to query without the calling code needing to know.
This keeps your business logic, fraud rules, and feature code identical across regions, which matters enormously for maintenance and for the honest answer to “does every region get the same bug fixes at the same time.” The complexity moves into the routing and shard-resolution layer, which is a much smaller surface area to get right and to audit than your entire application tier.
Schema migrations need the same discipline. A migration framework that applies changes shard by shard, in a defined order, with rollback per shard, keeps a schema change in Singapore from silently drifting out of sync with the same table in Ireland.
The parts people forget: backups, logs, metadata, and support tickets crossing borders anyway
A sharding strategy can be architecturally correct and still fail compliance because of everything built around it. This is the part of the outline that catches teams who did the hard database work and assumed that was the whole job.
- Backups. If your backup job streams every shard’s snapshot to a single centralized object store for operational simplicity, you’ve just undone the entire residency strategy. Backup destinations need the same jurisdiction mapping as the primary data, and backup retention schedules need to respect the same rules, since a backup is still a copy of the regulated data.
- Logs. Application logs, especially at debug or verbose levels, routinely capture customer IDs, request payloads, or full database rows during error handling. If those logs ship to a centralized logging platform in a different country, you have personal data crossing a border through a side channel nobody flagged as in scope.
- Metadata and caches. Search indexes, caching layers, and analytics pipelines often pull from every shard into one place because that’s operationally convenient. Each of those is a copy of regulated data, and each needs its own jurisdiction-aware design, not an exemption because “it’s just a cache.”
- Support tooling. A support agent pulling up a customer’s record in a centralized CRM or ticketing system, regardless of where that agent or that customer sits, is moving data across the same border the sharding strategy was built to respect. If your support stack isn’t shard-aware, it’s your weakest point, and it’s also the one regulators ask about because it’s the easiest to demonstrate in an audit interview.
Every one of these needs to appear on the same jurisdiction map you built for the schema. A sharding strategy that stops at the primary tables and ignores its own exhaust is not finished.
Where multi-region transactions break and what trade-offs you’re actually accepting
Cross-border transactions are where residency and database consistency pull against each other directly. A payment between a customer in France and one in Brazil touches two jurisdictions, and a strict residency reading says each side’s data should live under its own country’s rules, which immediately raises the question of where the transaction record itself lives, since it references both.
There’s no version of this that avoids a trade-off. Storing the full transaction record in both jurisdictions means duplicating data and accepting the reconciliation burden of two copies that must stay consistent. Storing it in one jurisdiction and referencing it from the other means one side has a technically incomplete local record, which some regulators accept and others don’t. Splitting the record into jurisdiction-specific views, where each side stores only the fields relevant to its own subject and a settlement layer ties them together, is the approach most multi-region fintechs land on, but it adds real complexity to reconciliation and to any downstream reporting that expects a single, complete transaction object.
Multi-region transactions also break the usual assumptions behind distributed transactions and two-phase commit, because a coordinator that spans jurisdictions is itself a data flow across a border during the commit process. Teams that have worked through the equivalent problem in GDPR-compliant architecture generally end up accepting eventual consistency across shards for cross-border operations, with a reconciliation job that resolves mismatches on a schedule, rather than insisting on strong consistency that would require data to cross a border at transaction time anyway.
Proving compliance: what auditors want to see from your sharding setup
An auditor is not going to be satisfied by a diagram showing shards labeled with country names. They want evidence that the system enforces the mapping, not just that it was designed to follow it. In practice, that means being ready to produce:
- The jurisdiction map itself, showing which tables and fields are in scope and how each one resolves to a shard.
- Query logs or routing layer logs that demonstrate reads and writes for a sample of customer records actually landed on the correct node.
- A backup inventory showing where each shard’s backups are stored and confirming no centralized backup pipeline bypasses the mapping.
- Evidence that logging, caching, and support tooling were included in the scope review, not just the primary database.
- A record of how the system handles a customer who changes jurisdiction, since that edge case reveals whether the mapping is actually enforced or just assumed.
That last point is worth taking seriously on its own. A customer moving from one regulated jurisdiction to another is a routine event, and a system that can’t show how it re-shards or migrates that customer’s data is a system that hasn’t actually tested its own compliance story.
Pull up your own data map and check whether backups, logs, or support tooling are moving data across the same borders your sharding strategy was built to respect.