
Choosing an API provider for payments, banking data, or identity verification often gets treated like choosing a SaaS tool: compare feature lists, check the pricing page, pick the one with the nicest logo wall. That approach works for a project management app. It does not work for something that sits in the path of every transaction your product processes, where a bad integration choice shows up months later as a 2am page, a breaking change nobody warned you about, or a support ticket that sits unanswered while customers can’t complete a payment.
This guide covers the technical and operational traits that actually separate a reliable integration partner from one that will cost you an engineering quarter. It does not cover compliance certifications, financial stability, or vendor risk scoring in depth. For that side of the evaluation, the vendor risk framework is the better reference.
What counts as an integration partner, not just an API vendor
An API vendor sells you access to an endpoint. An integration partner takes responsibility for what happens when that endpoint is part of your production system for years, through their version changes, their outages, and your scale.
The distinction matters because the sales process looks identical from the outside. Both will show you a clean API reference, a quickstart guide, and a demo that works. What differs is what happens after the contract is signed: how they communicate breaking changes, how fast they respond when your integration breaks at a bad hour, and whether their sandbox behaves anything like their production environment.
A useful filter during evaluation is to ask not “can this API do what I need” but “what happens on the worst day I’ll have with this provider.” Most API vendors can answer the first question well. Few can answer the second with anything more specific than a general promise of reliability.
Reading the docs and sandbox before you read anything else
Documentation quality is one of the few things you can evaluate in an afternoon, and it tells you more about engineering culture than almost anything else available before you sign.
Look for:
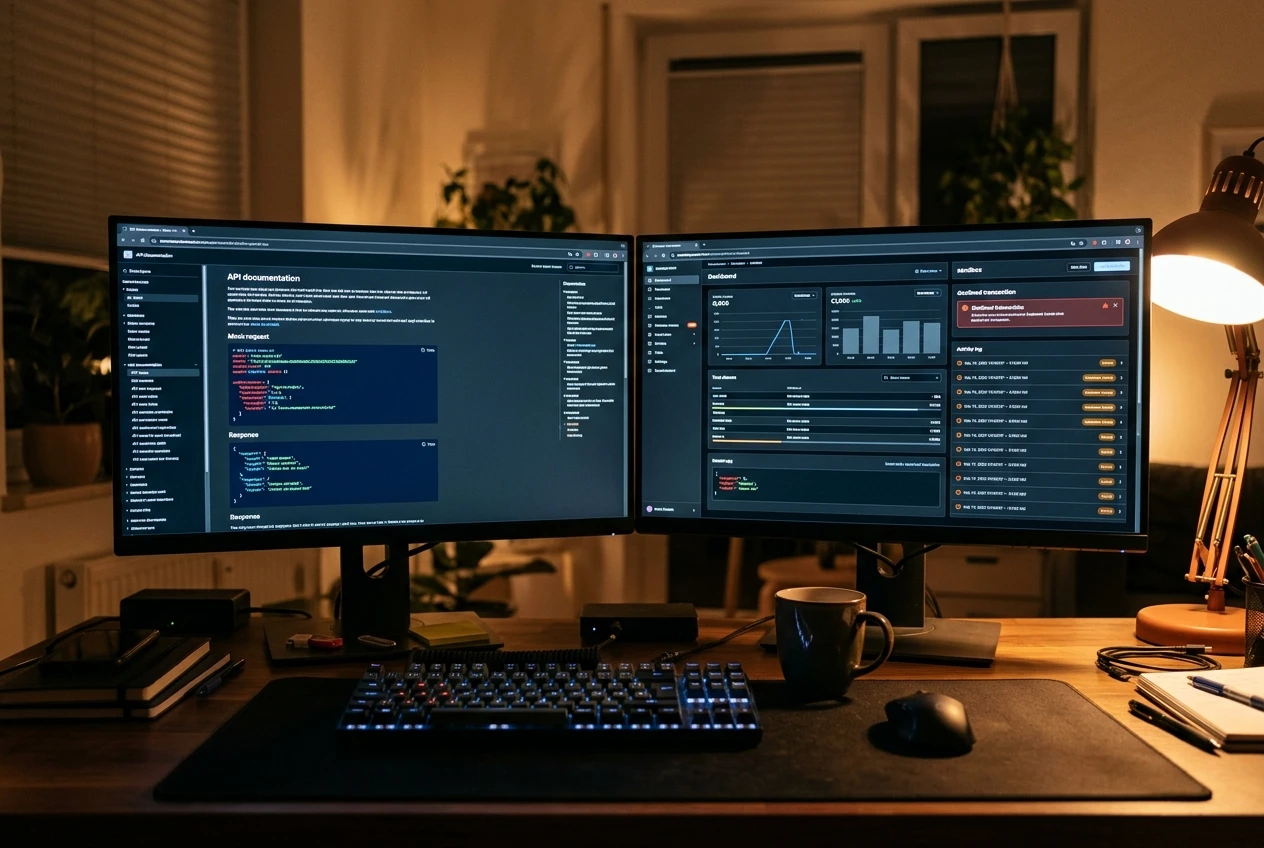
- Complete request and response examples for every endpoint, not just the happy path. If error responses are listed as a single generic table with no example payloads, assume your engineers will be reading error codes off a support forum later.
- Changelogs with real dates and specific detail, not a vague “improvements and bug fixes” entry repeated every release.
- Idempotency key support documented clearly, with an explanation of exactly how long keys are honored and what happens on retry.
- Rate limit documentation that states actual numbers, not “contact us for your limits.”
The sandbox matters as much as the docs, and it’s where a surprising number of providers cut corners. A sandbox that only returns success responses teaches your team nothing about how the integration behaves under failure. Test these specifically before you build anything meaningful:
- Declined transactions, timeouts, and partial failures, not just approvals
- Webhook delivery, including delayed and out-of-order delivery
- Realistic latency rather than instant responses that production will never match
If the sandbox can’t simulate a declined card, an expired token, or a webhook that arrives twice, your team will discover those behaviors for the first time in production, with real customers on the other end of the failure.
What the SLA actually promises versus what it sounds like it promises
SLA pages are written to sound reassuring, and most of them are structured so that the reassuring part is true while the specific commitment is much narrower.
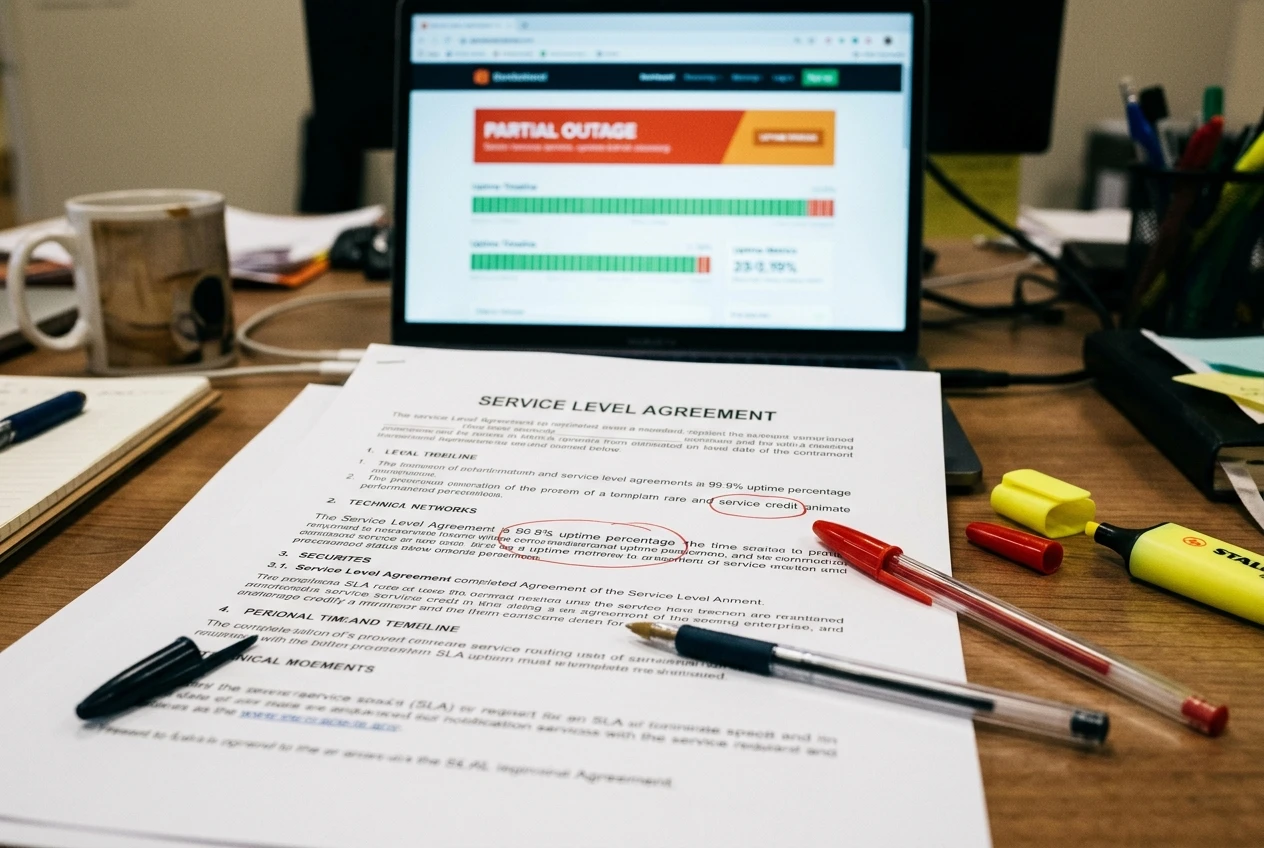
“99.9% uptime” sounds strong until you read the definition of uptime being measured. Some providers measure uptime at the load balancer, which can be up while the actual API processing layer is degraded or returning errors. Ask directly what is and isn’t counted: scheduled maintenance windows, partial degradation, elevated error rates that don’t technically constitute an outage.
Check what the remedy actually is when the SLA is breached. Most SLAs offer service credits, a percentage of monthly fees refunded as account credit toward future billing. That credit does nothing for the revenue lost or the customer trust damaged during an outage that took your payment flow down for three hours. Read the remedy section as a statement of what the provider is actually on the hook for, not as a statement of how reliable the service will be.
Also check the SLA’s carve-outs for third parties. A payments API that depends on card networks or banking rails for parts of its flow will often exclude outages caused by those upstream providers from its own uptime calculation. That’s reasonable in principle, but it means the SLA covers less of your actual failure surface than it appears to.
How a provider handles versioning and deprecation without breaking your production code
Versioning discipline is one of the clearest signals of how a provider treats its existing customers versus its newest ones.
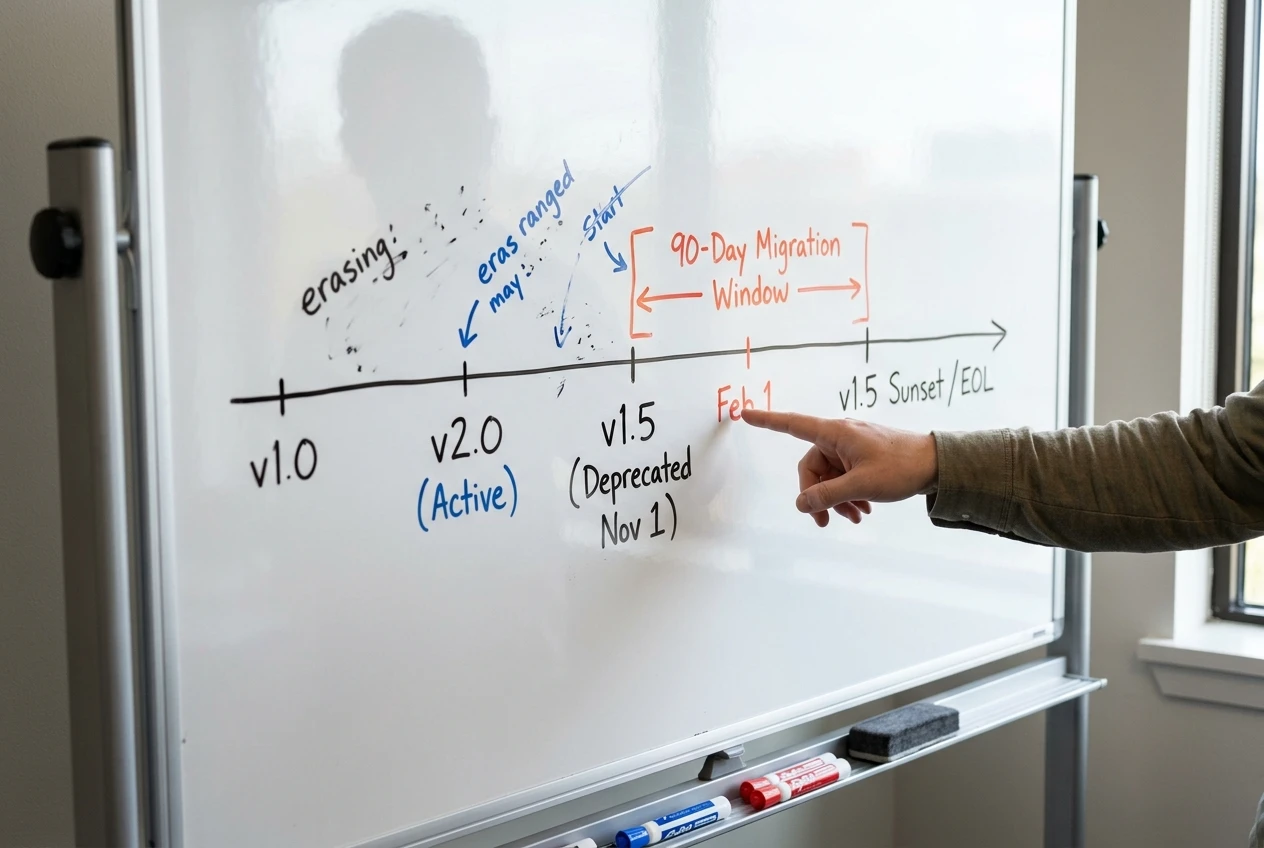
Ask specifically:
- How long are old API versions supported after a new version ships
- Is there a dated deprecation notice period, and how is it communicated (email, dashboard banner, changelog only)
- Do breaking changes ever ship within a version, or only at major version boundaries
- Is there a way to pin to a specific API version indefinitely, or does the provider force migration on a timeline
A provider with real versioning discipline treats a version number as a contract: once shipped, that version’s behavior doesn’t change underneath you. A provider without it will describe changes as “minor” that are, in practice, breaking, because the internal definition of “minor” means “doesn’t break our own test suite,” not “doesn’t break yours.”
This is worth testing before you sign, not just asking about. Look at the actual changelog history for a pattern of silent behavior changes inside a stated version, field additions that change existing validation logic, or deprecation notices that gave customers less than 90 days to migrate. A provider’s past versioning behavior is a far better predictor than anything in a sales conversation.
Support response times when the integration fails at 2am
Every provider will tell you they offer 24/7 support. The question that matters is what that support actually does in the first thirty minutes of a production incident.
Specific things to pin down before signing:
- What is the guaranteed first-response time for a severity-one incident, in writing, not as a verbal estimate
- Is there a dedicated incident channel (phone, dedicated Slack, status page with direct engineer access) or does every ticket go into the same queue regardless of severity
- Does the support tier you’re paying for include access to engineers who can actually read logs and diagnose, or only to a first-line team that escalates internally with no visibility for you
- What does the provider’s own status page look like historically: are incidents disclosed promptly and with real detail, or do outages quietly resolve with no public acknowledgment
A good way to get a real answer rather than a sales answer is to ask to speak with an existing customer on a similar plan tier, specifically about a recent incident. Providers confident in their support response will arrange this. Providers who hesitate are telling you something.
Pricing models and where the hidden costs of scale show up
Per-transaction pricing is easy to model at your current volume and easy to misjudge at your future volume. The places hidden costs show up most often:
- Tiered pricing that drops per-transaction cost at higher volume but adds a minimum monthly commitment that locks you in before you’re sure of your growth curve
- Separate charges for webhook retries, sandbox usage beyond a free tier, or additional environments (staging, QA) beyond production
- Charges for identity verification or KYC checks that are billed per attempt rather than per successful verification, which matters a great deal if your funnel has any retry logic
- Data retention or export fees that only appear when you need historical transaction data for a dispute or an audit, well after the initial contract is signed
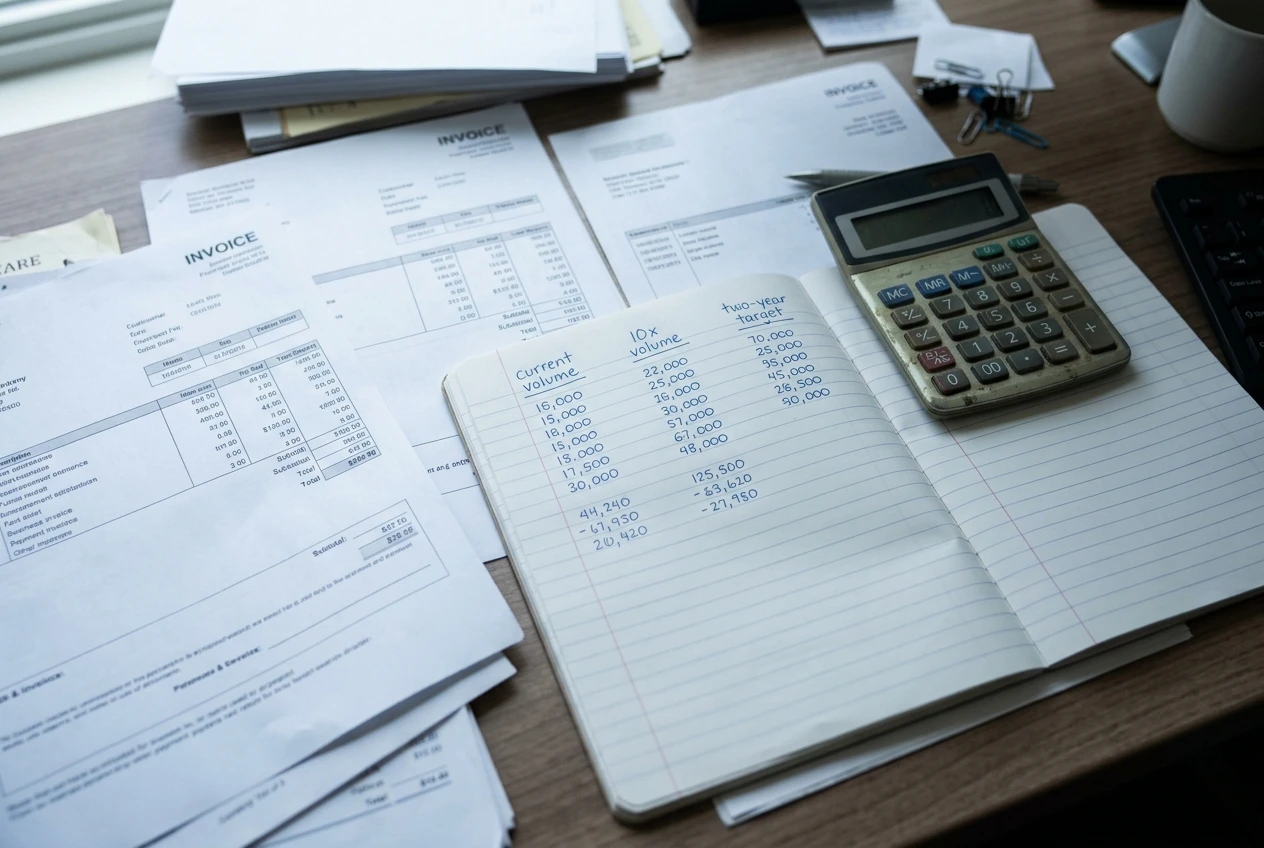
Ask for a pricing breakdown at three volume points: your current volume, 10x that, and a volume you consider a reasonable two-year target. A provider whose pricing model was built around a specific scale that it expects you to exceed will show awkward jumps in that projection. That’s worth knowing before you build a year of integration work on top of it.
Security and compliance certifications worth verifying before you sign
A technical evaluation on its own will miss several things that only a structured vendor assessment catches, including financial stability, data handling agreements, breach history, and the specific certifications relevant to your regulatory footprint (PCI DSS, SOC 2 Type II, ISO 27001, and others depending on what the integration touches). These matter enormously, and they deserve their own process rather than a quick checkbox during a technical review.
Running a 30-day side-by-side trial before committing
If you’ve narrowed the field to two finalists on technical grounds, the most reliable way to choose between them is to run both integrations against a non-critical slice of real traffic for 30 days before signing a long-term contract with either.
During that window, track specifically:
- Actual latency under your real traffic patterns, not sandbox numbers
- How each provider’s support team responds to a real, if minor, incident you raise deliberately
- Whether documentation matches actual behavior for edge cases you’ve identified as important to your product
- Webhook reliability and delivery timing under your actual load
Thirty days is enough time to surface the gap between what a sales deck promises and what a production environment delivers, and it’s cheap insurance relative to the cost of migrating off a provider a year into a contract.
A technical evaluation covers documentation, versioning, support, and pricing, but it won’t catch everything a provider might be hiding on the compliance and risk side. Before signing a contract, run the finalist through the fintech vendor risk assessment checklist to catch what a technical evaluation alone will miss.