
A payment platform built to handle a few thousand transactions a day runs on decisions that made sense at that volume: a single database, one region, maybe a handful of application servers behind a load balancer. None of those decisions were wrong. They were sized correctly for the problem in front of them. The trouble starts when transaction volume grows tenfold and nobody revisits the sizing.
This is the pattern behind most fintech outages that make the news. The system did not fail because an engineer made an obvious mistake. It failed because an architecture built for one order of magnitude was asked to run at the next one, under the same reliability expectations regulators and customers already assumed it met. This piece looks at the specific tradeoffs involved in cloud architecture for fintech scalability: where capacity breaks first, what multi-region design actually costs you, and how to keep five-nines reliability intact while the transaction count climbs from thousands to millions.
Why the infrastructure that works at launch breaks at scale
Early-stage fintech infrastructure is usually optimized for speed of shipping, not for load. A single relational database handles every write. One cloud region serves every customer. Background jobs run on a schedule because nobody is checking latency under contention yet. At low volume, this works fine, and spending engineering time hardening it would have been wasted effort.
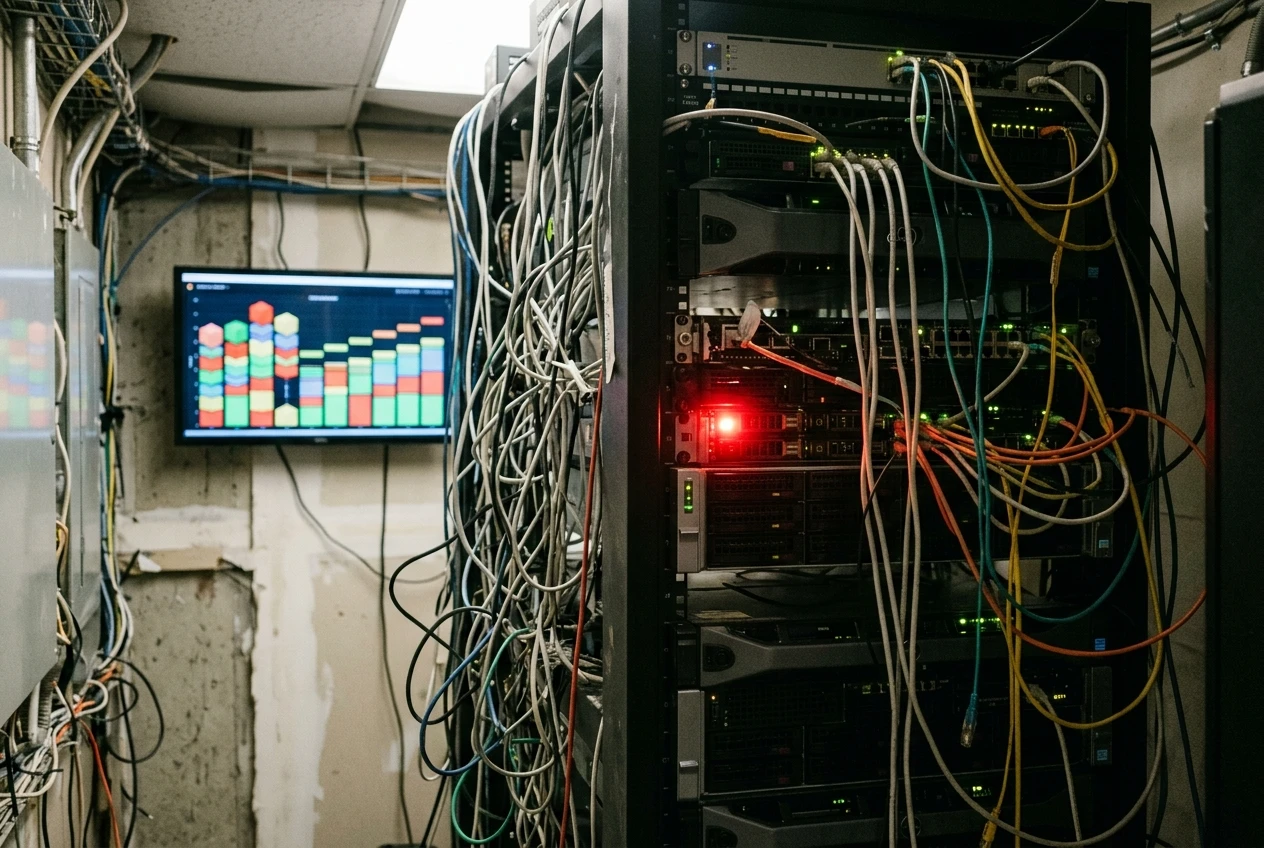
The first place this breaks is usually the database. Connection pools exhaust. Write locks on a popular table start queuing transactions behind each other. A process that took 200 milliseconds at launch takes four seconds under load, and now customer-facing timeouts start appearing in support tickets before anyone on the engineering team sees them in a dashboard.
The second place it breaks is failure isolation. In a tightly coupled system, a slowdown in one function, say, fraud scoring, backs up into the checkout flow, and a problem that should have affected one feature takes down the whole platform. At low transaction volume this rarely happens because there is enough slack in the system to absorb a slow dependency. At high volume, there is no slack left.
The fix is not a single migration. It is a series of architectural decisions, each with a real cost, made deliberately rather than reactively after an outage.
Multi-region architecture: the latency, data residency, and compliance tradeoff
Running in multiple cloud regions is often pitched as a straightforward reliability upgrade: more regions, more redundancy, fewer outages. In fintech, it is more complicated than that, because every region you add changes your latency profile, your compliance obligations, and your data residency posture at the same time.
Latency is the easiest tradeoff to see. A customer in one part of the world transacting against a database in another region will feel the round trip, and for payment authorization specifically, that delay is visible to the customer at the exact moment they are least patient. Serving customers from the nearest region solves this, but it means your data, and potentially your transaction processing logic, now lives in more places, which is where the harder tradeoffs start.
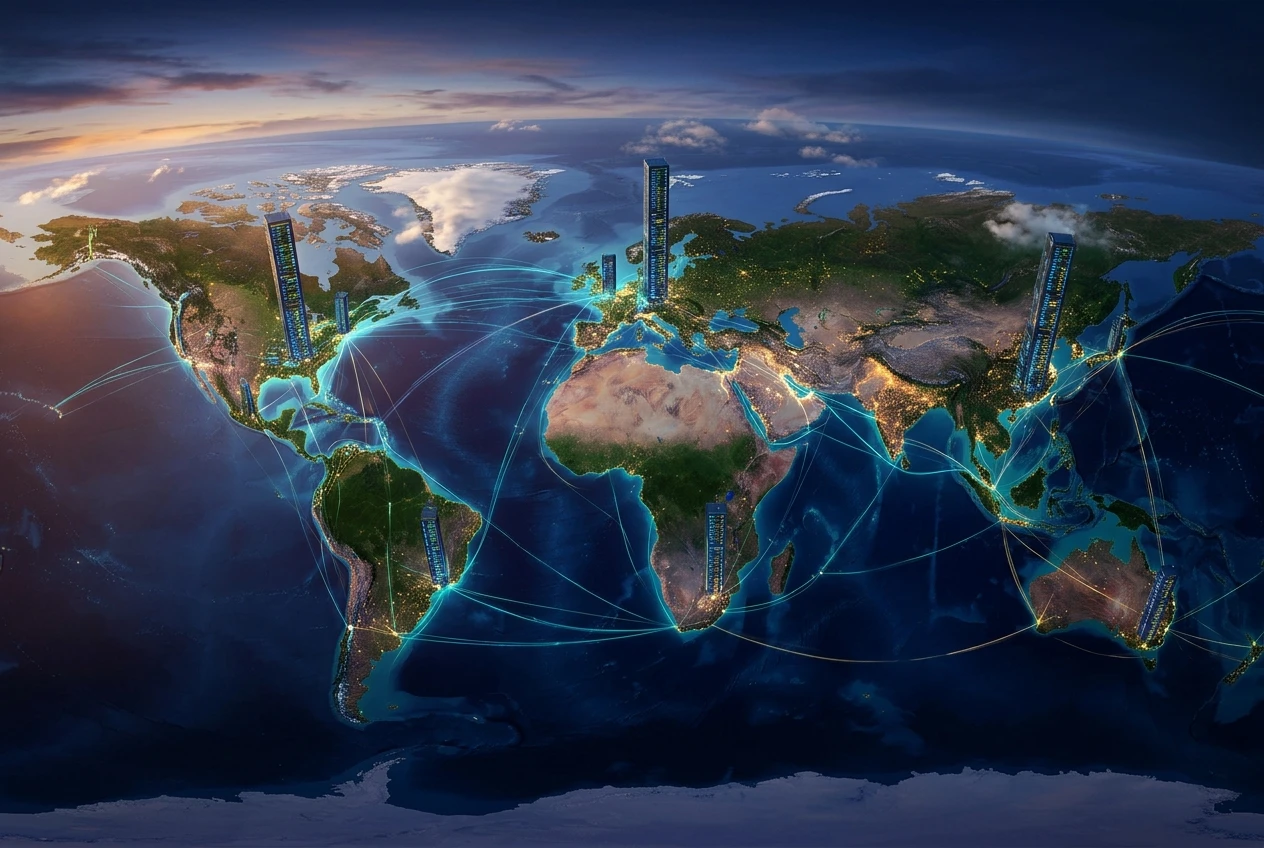
Data residency rules vary by jurisdiction, and some regulators require that financial transaction data for their citizens stay within specific borders. A multi-region architecture that was designed purely for latency and failover can put a fintech in violation of a residency requirement it didn’t know applied, simply because a replica of customer data now lives in a region the regulator didn’t authorize. This is worth designing for explicitly, not discovering after the fact, and it is a large part of why a founder’s roadmap to fintech compliance treats infrastructure decisions and compliance obligations as something to plan together rather than in sequence.
The practical approach most fintechs land on is a hybrid: a primary region for core transaction processing with strict consistency requirements, and regional read replicas or edge services for latency-sensitive, lower-risk operations like balance checks or account lookups. Full active-active multi-region writes, where every region can accept and commit transactions independently, is the hardest version of this to get right and the most expensive to operate. It is worth it for platforms operating at genuinely global, high-volume scale. It is usually not worth it before that.
Auto-scaling transaction processing without sacrificing consistency
Auto-scaling compute is the easy part of this problem. Spinning up additional application servers in response to load is a solved problem on every major cloud provider. The hard part is scaling the parts of the system that touch money, because those parts cannot simply be duplicated the way stateless web servers can.
A transaction processing pipeline has to guarantee that a payment is recorded once, not twice, even when ten application instances are all handling requests concurrently under load. This is where idempotency keys, distributed locking, and careful database transaction design matter more than raw compute capacity. Adding more servers without solving for consistency just means more things racing to write to the same ledger row at the same time.
The pattern that holds up under growth is separating the parts of the system that can scale horizontally without constraint, like API gateways, authentication, and fraud scoring, from the parts that need strict ordering and consistency, like ledger writes and settlement. The first group can auto-scale aggressively. The second group scales by sharding carefully, by transaction type, by account range, or by region, rather than by simply adding more instances pointed at the same data. This is also where a platform’s approach to real-time payment settlement intersects directly with its architecture, because the operational discipline that real-time settlement demands maps closely onto the consistency guarantees a scaling transaction pipeline needs.
What ‘financial-grade reliability’ actually requires: redundancy, failover, and disaster recovery
Five-nines reliability, 99.999% uptime, allows for roughly five minutes of downtime a year. That number sounds abstract until you translate it into architecture: it means no single point of failure is acceptable anywhere in the critical path, and recovery from a failure has to happen in seconds, not the hours a smaller platform might tolerate.
Redundancy means every critical component, application servers, databases, message queues, has at least one standby ready to take over without a manual intervention. Failover means the system detects a failure and routes around it automatically, and the detection has to be fast enough that customers don’t notice. A failover that takes three minutes to trigger because a health check runs too infrequently is, for practical purposes, an outage.
Disaster recovery is the layer above failover: the plan for when an entire region goes down, not just a single server. This requires a genuinely tested recovery process, not just a document describing one. Backups that have never been restored in a drill are a liability dressed up as a safety net. The recovery time objective, how long it takes to get back online, and the recovery point objective, how much data you can afford to lose, need to be defined numbers that engineering leadership has agreed to, not aspirations.
None of this is free, and building financial-grade reliability from day one for a platform processing a few hundred transactions a day is over-engineering. The architecture decision is about building the system so that this level of redundancy can be added in layers as volume grows, rather than needing a rebuild each time.
Microservices versus monolith: when splitting the system is worth the complexity
Splitting a monolith into microservices is often framed as an obviously correct move for any system expecting growth. It isn’t automatic, and the complexity cost is real: more services means more network calls, more places for a request to fail, more operational overhead in monitoring, deployment, and debugging.
The case for splitting out a service is strongest when a specific part of the system has a genuinely different scaling profile or reliability requirement than the rest. Fraud scoring, for example, might need to scale independently and can tolerate brief degraded performance without taking down checkout. Ledger writes need strict consistency and should probably stay isolated regardless of architecture style, because mixing them into a general-purpose service makes it harder to reason about correctness.
The mistake worth avoiding is splitting services prematurely, before there’s a clear scaling or reliability reason to do it, just because microservices are the pattern larger companies use. A monolith with clean internal boundaries, where the code is organized so that a future split is possible without a rewrite, is often the right choice for a fintech still finding its transaction volume. The split becomes worth the complexity when a specific component is genuinely bottlenecking the rest of the system, not before.
The cost trap: when a growing cloud bill outpaces growing revenue
Cloud costs scale differently than most founders expect. Compute costs tend to scale roughly linearly with transaction volume, which is manageable. Data transfer costs, especially across regions, and the cost of maintaining redundant standby infrastructure that sits mostly idle waiting for a failover, scale less predictably and can grow faster than revenue if nobody is watching.
The specific trap in fintech is that reliability requirements push toward redundancy, and redundancy means paying for capacity that, most of the time, does nothing. A standby database replica, a second region kept warm for failover, extra compute headroom for traffic spikes: all of this is necessary, and all of it shows up on the bill whether or not it’s ever used.
Managing this well means treating cost as an architecture input from the start, not a finance problem to deal with later. Right-sizing reserved capacity against measured, not guessed, baseline load; using auto-scaling to handle spikes rather than permanently provisioning for peak; and reviewing which regions and redundancy layers are actually earning their cost against the compliance or latency requirement they were built for, rather than keeping them because removing them feels risky.
Picking a cloud provider: hyperscalers versus fintech-specialized platforms
The major hyperscalers, AWS, Google Cloud, and Azure, offer the broadest set of building blocks and the most mature multi-region tooling, which matters for a fintech planning to operate across several jurisdictions. They also require the fintech itself to assemble compliance-relevant configuration, like data residency controls and audit logging, correctly, since the platform gives you the tools but not the fintech-specific defaults.
Fintech-specialized cloud platforms and banking-as-a-service infrastructure providers trade some of that flexibility for defaults built around financial services compliance requirements, which can shorten the path to launch considerably for a team without deep infrastructure expertise in-house. The tradeoff is less control over the underlying architecture and, in some cases, a harder path if you later need capabilities the specialized platform doesn’t offer.
There isn’t a universally correct answer here. A fintech with strong in-house infrastructure expertise and ambitions to operate across many regions usually gets more long-term value from a hyperscaler, built carefully. A fintech moving fast with a smaller engineering team often gets to a reliable, compliant platform faster on specialized infrastructure, even if it means revisiting the decision later as volume and ambition grow.
Scaling infrastructure to this level tends to surface new compliance obligations at the same time, since data residency, audit logging, and disaster recovery requirements often shift as you cross volume and jurisdiction thresholds. Pair this with a founder’s roadmap to fintech compliance to see what to handle at each stage of growth.