
Every double-entry ledger has the same bottleneck hiding under a different name. It looks like a throughput problem, or a database sizing problem, or a “why does this endpoint spike under load” problem. It is almost always a locking decision, made once during the first schema design and never looked at again, that determines how many concurrent writers the ledger can actually sustain before balances start to drift or transactions start to queue.
That decision matters more for ledgers than for almost any other kind of write path. A double-entry posting touches at least two rows, the debit account and the credit account, and both rows have to update together or not at all. Under low traffic this is invisible. Under real traffic, with thousands of accounts posting concurrently and some accounts (a popular merchant, a clearing account, a suspense account) receiving a disproportionate share of writes, the locking strategy decides whether the system degrades gracefully or falls over in a way that takes the whole ledger with it.
Why ledger writes are the concurrency bottleneck no one plans for
A ledger posting is not one write, it is a pair of writes that must be atomic and must leave both rows in a state that is correct relative to every other posting touching those same two accounts. That pairing is what makes ledgers different from most transactional workloads. A typical e-commerce order touches one row that matters for correctness. A ledger posting touches two, and those two are often chosen by two different transactions at the same moment, which means the opportunity for conflict is built into the data model rather than being an edge case.
The accounts that cause trouble are predictable: settlement accounts, fee accounts, FX clearing accounts, anything that every transaction passes through. These “hot” accounts receive far more concurrent writes than an individual customer account ever will, and they are usually the rows where a locking strategy chosen for the average case starts to fail. Teams size their database for average transaction volume and then discover that three or four accounts are carrying load the rest of the schema was never designed around.
The fix is not a bigger database. It is picking a locking mechanism that matches how contention actually distributes across the ledger, and that choice has to be made with the hot accounts in mind, not the median ones.
Pessimistic locking: row-level locks and when they actually help
Pessimistic locking takes a row lock before reading the balance, holds it through the update, and releases it on commit. In most relational engines this means SELECT ... FOR UPDATE on both the debit and credit rows, inside a single transaction, before any balance arithmetic happens. Every other writer trying to touch either row has to wait.
This works well when contention on any single account is moderate and the transaction is short. The lock is held for milliseconds, the writer that was waiting proceeds immediately after, and the ledger stays consistent without any retry logic in the application layer. For most customer-to-customer transfers, where the odds of two postings hitting the same account in the same millisecond are low, pessimistic locking is simple and correct and nobody has to think hard about it.
It stops working well on hot accounts. If a clearing account is touched by hundreds of postings per second, pessimistic locking turns that account into a serialization point: every writer queues behind the one currently holding the lock, and throughput on that account becomes a function of how fast a single lock can be acquired and released, not how many database nodes you have. Adding read replicas does not help, because replicas do not take write locks. The queue is real and it is on the primary.
Pessimistic locking also needs discipline around lock ordering. If one transaction locks account A then B, and another locks B then A, you have the setup for a deadlock, which the next section covers directly. The rule that keeps pessimistic locking safe is simple to state and easy to skip under deadline pressure: always acquire locks in a fixed, deterministic order, regardless of which account is the debit side and which is the credit side.
Optimistic concurrency control: version columns, retries, and when they break down
Optimistic concurrency control (OCC) assumes conflicts are rare and checks for them at commit time instead of blocking at read time. The common pattern adds a version column, or uses the balance itself as the compare value, and the update statement includes a WHERE version = expected_version clause. If no row matches, the application knows another writer got there first, and it retries the whole operation against the fresh state.
OCC avoids the queuing problem that pessimistic locking has on hot accounts, because nothing is held while a writer is thinking. Readers never block writers, and writers never block each other while computing the new balance. For ledgers where most writes touch distinct account pairs and real conflicts are infrequent, OCC can push through significantly more concurrent transactions than row locking, because the database spends no time waiting.
It breaks down exactly where pessimistic locking does, but in a different way: on hot accounts, instead of a queue you get a retry storm. If a clearing account is updated by hundreds of transactions per second, a large fraction of those optimistic writes will lose the version race and have to recompute and resubmit. Under enough contention, the retry rate climbs faster than throughput does, and the system can spend more work retrying than it does committing. OCC also needs a bounded retry count and a clear failure path; an unbounded retry loop on a hot account under load is how a traffic spike turns into a cascading backlog.
The practical pattern many ledgers land on is mixed: OCC for the bulk of account-to-account postings, and pessimistic locking reserved specifically for the small number of accounts known to be hot. That split requires knowing your hot accounts in advance, which is worth instrumenting for directly rather than discovering during an incident.
Deadlocks in double-entry postings and how to avoid them by design
A deadlock in a ledger almost always comes from two transactions locking the same two accounts in opposite order. Transaction one locks account A, then tries to lock account B. Transaction two has already locked B and is waiting on A. Neither can proceed, and the database eventually kills one of them with an error that looks mysterious if you aren’t expecting it.
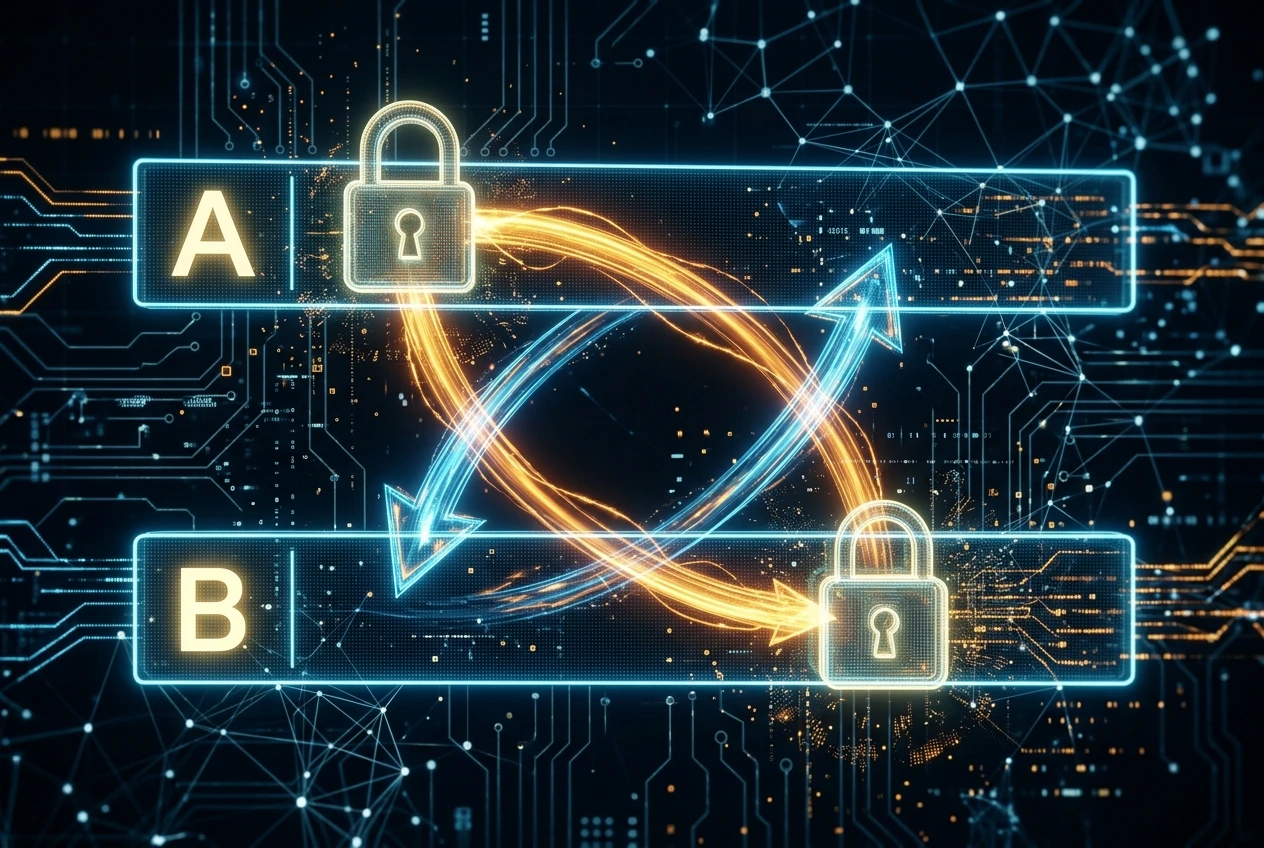
The fix is structural, not procedural: never let the application choose lock order based on which account is the debit and which is the credit. Instead, sort the two account identifiers before locking, by a stable key like account ID, and always lock the lower one first. This removes the possibility of circular waits entirely, because every transaction touching accounts A and B, regardless of direction of funds, acquires locks in the same order.
This single rule, enforced in one place in the code, generally eliminates ledger deadlocks that come from posting logic. It does not eliminate deadlocks that come from unrelated queries touching the same rows, like a reporting job that reads a range of accounts under a lock. Keep reporting and reconciliation reads out of the transactional path, or run them against a replica, so they never compete for the same locks as live postings.
Isolation levels: why serializable isn’t always the safe default
Serializable isolation is the instinct for ledger correctness: it guarantees that concurrent transactions behave as if they ran one after another, which sounds like exactly what a ledger needs. In practice it is the isolation level most likely to produce serialization failures under load, because the database has to detect and reject any transaction whose read set could have been affected by a concurrent write, even when the actual accounts involved never overlap.
Under high concurrency, serializable isolation can reject a meaningful fraction of transactions that were never actually in conflict, simply because the database’s conflict detection is coarser than the real dependency graph. Every rejected transaction needs an application-level retry, and at scale that retry traffic becomes its own load problem, layered on top of the original write load.
Repeatable read, combined with explicit row locking on the specific accounts a transaction touches, often gives the same practical guarantee for ledger postings without the false-positive rejection rate. The correctness property a ledger actually needs is that no two transactions can both read and update the same account balance without seeing each other’s effect, not that every transaction in the system is globally serializable with every other one. Explicit locking on the rows that matter achieves the narrower, sufficient guarantee at a much lower cost than asking the isolation level to enforce a broader one it doesn’t need.
Serializable isolation still has a place for the parts of the system where correctness genuinely depends on cross-account invariants holding across more than two rows, such as multi-leg settlement batches. The mistake is reaching for it as the default for every posting path without checking whether the narrower guarantee from row locking already covers the real requirement.
Distributed locking across sharded or multi-region ledgers
Once a ledger is sharded by account, or replicated across regions for latency or residency reasons, locking stops being a single-database problem. A transfer between two accounts on different shards cannot rely on a local row lock, because the two rows being locked are on different nodes with no shared lock table.
Distributed locks, usually built on a coordination service or a consensus-backed lock store, solve this but introduce a new failure mode: the lock holder can crash or get network-partitioned away while still holding the lock, and every approach to this trades off against the others. Lease-based locks with short timeouts recover automatically but can release a lock while the holder is still working, mid-transaction, if the timeout is too aggressive. Fencing tokens, a monotonically increasing number attached to each lock grant, prevent a stale lock holder from writing after its lease expired, and are close to mandatory for any distributed lock protecting ledger writes.
The alternative many sharded ledgers converge on is avoiding distributed locks for the common case entirely, by routing cross-shard transfers through a two-phase commit or saga pattern instead: reserve on both shards, confirm on both shards, compensate if either side fails. This trades strict locking for an explicit compensation path, which is more code but fails in a way that is visible and recoverable rather than invisible and stuck. For ledgers spanning regions for data residency or latency reasons, the sharding and consistency trade-offs run deeper than locking mechanics alone, and that’s worth treating as its own design question rather than an extension of a single-region locking choice.
Matching a locking strategy to your throughput and failure tolerance
None of these mechanisms is categorically correct. The right choice depends on two numbers most teams can measure but rarely write down: the write rate on your hottest accounts, and how much latency or retry overhead you can tolerate before it shows up to users as a failed or delayed transaction.
A rough way to think about it:
- Low contention, correctness-critical, latency-tolerant: pessimistic row locking with deterministic lock ordering. Simple, predictable, easy to reason about during an incident.
- High write volume, low real conflict rate, mostly distinct account pairs: optimistic concurrency control with bounded retries, and pessimistic locking carved out for known hot accounts.
- Multi-leg or cross-account invariants that span more than two rows: serializable isolation scoped narrowly to that transaction type, not applied system-wide.
- Sharded or multi-region writes: saga-style reservation and confirmation over distributed locks, with fencing tokens if a distributed lock is unavoidable.
The decision is worth revisiting whenever transaction volume grows by an order of magnitude, because a strategy that held comfortably at a thousand postings a second can behave completely differently at ten thousand, and the accounts that become hot at scale are not always the ones that were hot at launch.
Locking strategy sits inside whatever database engine you’ve already chosen, but the engine choice itself shapes which of these mechanisms are even available to you, from how row locks behave under the hood to whether the system gives you native support for distributed transactions. If that underlying decision is still open, this comparison of NewSQL and NoSQL for high-concurrency financial transactions covers the engine-level trade-offs that this piece assumes are already settled.