
Most fintech engineering teams discover their architecture’s real shape only after the second or third country launch, not the first. The first new market usually fits inside whatever you already built for your home market, because you can route around its rough edges with a configuration flag, a currency table update, and a new compliance checklist item. The third market is different. By then you are carrying accumulated assumptions about latency, data location, and consistency that nobody wrote down, and at least one of those assumptions is wrong for the country you are about to enter.
This article is for the engineering leaders and infrastructure architects who have to make that call market by market: keep serving a new country from your existing data center, or stand up a regional deployment. The honest answer is that it depends on specifics you can actually check before you build anything, not on a general preference for centralization or for edge architecture. What follows is a framework for checking those specifics.
Why the first new market rarely breaks your architecture, and the third one usually does
A single centralized data center, serving one home market plus one adjacent country, hides a lot of sins. Latency from the second country to your primary region might add 40 to 80 milliseconds to an API call, which is tolerable for most fintech user flows outside of trading. Data residency rules in the second country might align closely enough with your home market’s rules that your existing controls satisfy both. Your on-call rotation can absorb one more region’s traffic pattern without anyone losing sleep over time zones.
None of that holds at market three. Latency compounds instead of staying flat, because you are often routing through infrastructure built for market one’s geography, not market three’s. Data residency requirements start to diverge in ways that a single rule set cannot satisfy, especially once you are mixing EU-style data protection regimes with country-specific financial data localization laws in markets like India, Indonesia, or Nigeria. And your on-call rotation, which worked fine for two time zones, starts producing 3 a.m. pages in a city where nobody on the team is awake.
The pattern worth noticing is that each new market adds strain in a different dimension, not more strain in the same dimension. That is why “it worked for the last two markets” is a weak argument for the third.
The real trade-off: latency, data residency, and blast radius, not just cost
Cost comparisons between centralized and regional architecture get discussed more than they deserve, because cost is the easiest number to put in a slide. The decision that actually matters runs through three other variables.
Latency is the most visible to users. A centralized data center in Frankfurt serving a new customer base in Singapore adds real, measurable delay to every request, and for a payment confirmation screen or a fraud check that blocks a transaction, that delay is the user’s experience of your product, not a footnote in an infrastructure review.
Data residency is the one with legal teeth. Some countries require that financial transaction data physically reside within national borders, with no exceptions for backup or disaster recovery copies. This is not a preference you can architect around with encryption or access controls. If the law says the data stays in-country, it stays in-country, and no amount of clever centralized design changes that.
Blast radius is the one engineering teams underweight. A single centralized data center means a single point of correlated failure: one outage, one bad deployment, one database corruption event, and every market you serve goes down at once. A regional architecture contains failures to the region where they happen, at the cost of needing to coordinate state across regions when things go right.
Weigh these three against each other for the specific market you are entering, not in the abstract. A market with lenient data residency rules, a geographically close data center option, and low transaction volume might not justify a regional deployment at all. A market with strict residency law, a large latency gap, and high expected volume almost certainly does.
When a single centralized data center still wins
Centralization is still the right default in several concrete situations. If the new market has no data localization requirement and sits within roughly 100 milliseconds of round-trip latency to your existing region, a single data center keeps your consistency model simple and your operational headcount flat. If transaction volume in the new market is expected to stay low for the first year or two, the cost of standing up a regional deployment will not pay for itself before you know whether the market is worth the investment at all.
Centralization also wins when your product’s core value depends on strong consistency across markets, such as a multi-currency wallet where a user can hold balances visible and spendable from any country they travel to. Splitting that ledger across regions introduces consistency problems that are hard to solve correctly, and if the markets involved do not force you to split, you should not split voluntarily. For teams building this kind of architecture, the broader question of how a cloud-based setup holds up under growth while keeping financial-grade reliability is worth working through in detail, which is covered in how cloud architecture lets fintechs scale without breaking financial-grade reliability.
When a regional edge deployment earns its complexity
A regional deployment earns its cost when at least two of the three variables above point the same direction. High latency plus high expected volume is the clearest case: if your new market’s users will feel every extra 100 milliseconds on a core flow, and there are enough of them to matter to the business, a regional presence pays for itself in conversion and retention alone.
Regulatory requirements that mandate in-country data storage make the decision for you, which the next section covers in more depth. But even without a legal mandate, a regional deployment is worth considering when the market is large enough that an outage in your home region, currently capable of taking down every market you serve, would create unacceptable business risk. Splitting a market into its own regional footprint shrinks your blast radius, and for a market carrying a meaningful share of your revenue, that containment is worth the added operational surface.
The complexity a regional deployment adds is real and should not be waved away: you now have two (or more) places where state lives, two places where deployments happen, and two places where something can go wrong independently. That complexity is a cost you pay in exchange for lower latency and smaller blast radius. It only earns its keep when the market is big enough or latency-sensitive enough to need both.
How data residency law can force the decision before you get to choose it
Some markets remove the choice entirely. India’s data localization requirements for payment system data, Russia’s data localization law, and sector-specific rules in countries like Indonesia and Vietnam all require that certain categories of financial data be stored, and sometimes processed, within national borders. When a market has a rule like this, the architecture decision is not a trade-off exercise, it is a compliance requirement, and the engineering question becomes how to meet it with the least disruption to the rest of your system.
This is also where teams get caught out late. Data residency law frequently covers not just primary storage but backups, logs, and in some interpretations, any system that can query or display the data, even if the underlying record stays in-country. A regional deployment built to satisfy “data storage must be in-country” can still fail an audit if your centralized logging or analytics pipeline pulls a copy of that data back to your home region for processing. Checking the actual scope of a residency law, not just its headline requirement, before committing to an architecture is worth the delay it costs. The broader discipline of designing for data protection regimes that keep tightening rather than loosening is covered in designing fintech architecture that survives GDPR and whatever regulation comes next, which applies beyond the EU to any jurisdiction with a strict data handling regime.
A hybrid pattern: centralized core ledger, regional edge for compliance and latency
Most fintechs operating across more than two or three markets end up somewhere between fully centralized and fully regional, and the pattern that recurs most often is a centralized core ledger with regional edge nodes handling compliance-sensitive data and latency-sensitive operations.
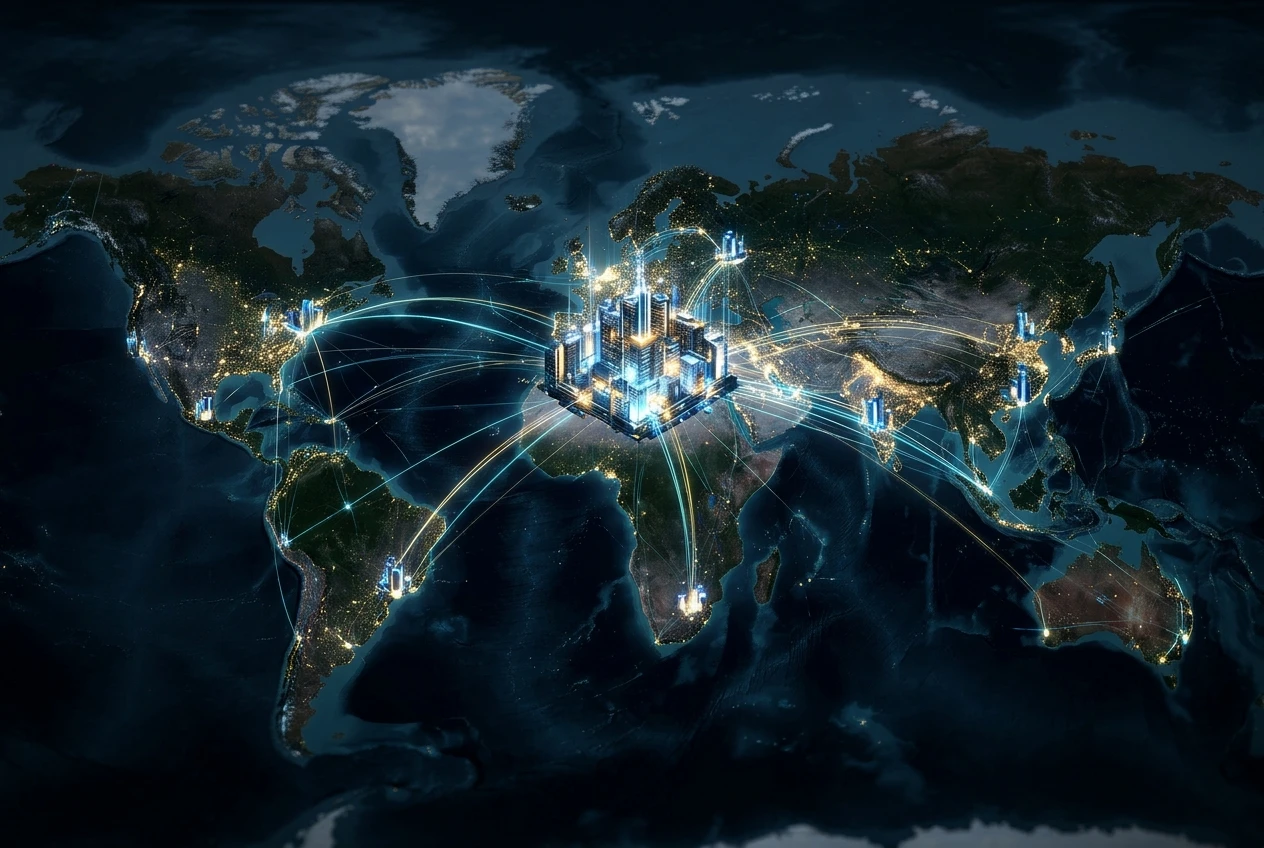
In this pattern, the system of record for account balances and transaction history stays in one place, preserving a single source of truth and avoiding the consistency problems of a split ledger. Regional nodes handle things that genuinely need to be local: KYC document storage where the law requires in-country retention, fraud scoring that needs sub-100-millisecond response times, and caching of frequently read data to cut latency for common user actions.
The hard part of this pattern is drawing the line correctly between what lives centrally and what lives at the edge. Draw it too conservatively, and you end up duplicating data across regions that did not need duplicating, adding reconciliation work for no compliance or latency benefit. Draw it too aggressively, and you end up with a regional node that thinks it has authoritative data when the central ledger disagrees, which is how reconciliation bugs make it into production. The line should follow the legal requirement and the latency requirement exactly, not a general instinct toward “more local is safer.”
The operational costs nobody budgets for: replication lag, consistency bugs, and follow-the-sun on-call
The infrastructure cost of a regional deployment shows up in the budget. The operational cost shows up later, usually in an incident review.
Replication lag between regions means that a balance update written in one region will not be instantly visible in another, and the gap, often measured in low hundreds of milliseconds under normal conditions, widens under load or during network issues between regions. If any part of your system assumes strong consistency across regions, that assumption will eventually be wrong at exactly the moment it matters, such as a user making two transactions in quick succession that both read a stale balance.
Consistency bugs born from this lag are some of the hardest to reproduce, because they only appear under specific timing conditions that a staging environment rarely recreates. Budgeting time for this class of bug, rather than assuming your testing will catch it, saves a production incident later.
Follow-the-sun on-call sounds appealing until you have built it. Covering multiple regions with local on-call staff means hiring or training engineers in each region who understand the full system, not just their region’s slice of it, because a cross-region consistency bug requires someone who can reason about both sides. Teams that underestimate this hire regional staff for local coverage, then discover that only the original team can actually debug the hard incidents, which defeats the purpose of regional on-call in the first place.
Building a per-market decision checklist before your next expansion
Before your next market entry, work through the same five questions for that specific country, rather than defaulting to whatever architecture served your last expansion.
- Does the market have a data residency or localization law that applies to your data categories, and does it cover backups, logs, and analytics, or only primary storage?
- What is the round-trip latency from your nearest existing region to this market’s major user base, and does that latency affect a core user flow?
- What transaction volume do you realistically expect in the first 12 to 18 months, and does it justify the fixed cost of a regional deployment?
- If your existing region went down, what would an outage in this market cost the business, and is that cost acceptable?
- Does your core ledger need strong consistency with this market’s data, or can the market operate with eventual consistency against the central system of record?
Answer these honestly for each market before you decide, and the architecture choice usually becomes clear rather than contentious. The markets where the answers point in different directions are the ones worth a longer design review before you commit engineering time to either path.